TaxoMine
Mining taxonomic knowledge from the scientific literature
Continues our work with biologists on extracting information about species from published papers, organised by taxonomy.
Group leader
oscarwilliam.lithgow@supsi.ch GitHubORCIDGoogle ScholarSemantic Scholar
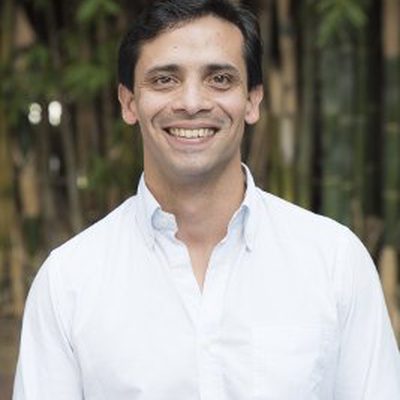
Oscar William leads the NLP group at IDSIA. His research covers meaning and similarity in text, how language models reason and handle uncertainty, and extracting knowledge from scientific and clinical text.
He holds a PhD in Computer Science from the National Autonomous University of Mexico (UNAM), on semantic similarity, and an MPhil in Computer Science with a focus on NLP from the University of Cambridge. During his PhD he worked with the Center for Genomic Sciences in Mexico, applying NLP to the curation of genomic literature in a project funded by the US National Institutes of Health.
Mining taxonomic knowledge from the scientific literature
Continues our work with biologists on extracting information about species from published papers, organised by taxonomy.
Semi-automated generation of discharge summaries
Helps doctors write discharge letters faster by drafting them from the patient record, for the doctor to check and complete.
Medical, multilingual and privacy-preserving NLP in the clinical domain
Makes modern language technology usable in Swiss hospitals: across the country's languages and without exposing patient data.
Conversational AI for energy-efficiency advice, a component of the ENERGENIUS project
A conversational interface where citizens ask in natural language about energy savings, costs and regulation.
NLP in support of pharmacovigilance: Quality Adverse Drug Reaction Active Control
Finds reports of adverse drug reactions in clinical text, to support drug-safety monitoring.
UBS–IDSIA AI Lab collaboration
The NLP group participates in the collaboration across different NLP-related projects.
Simplified and translated scientific literature for education
Used AI to produce simplified and translated versions of scientific papers for teaching.
Detecting misinformation and machine-generated text
Developed and tested ways to detect misleading content and text written by language models. Produced the BUST benchmark.
Mining arthropod traits from the literature
Built text-mining workflows and a database of traits of arthropods (insects, spiders, crustaceans and relatives) collected from the scientific literature.
Misinformation in social media during COVID-19
Studied how to identify misinformation on social media, and public stance towards health policies, during the pandemic.
Voice-based training simulations
With SkillGym, moved a leadership-training simulator from clicking options to speaking, using language understanding to follow the conversation.